Local AI workstations · quoted
VRAM, RAM and cooling sized for the models you actually run.
As model memory requirements come down, practical local inference is more accessible. The expensive mistake is still an 8-core CPU, a mid GPU and a costly board that cannot hold the weights.
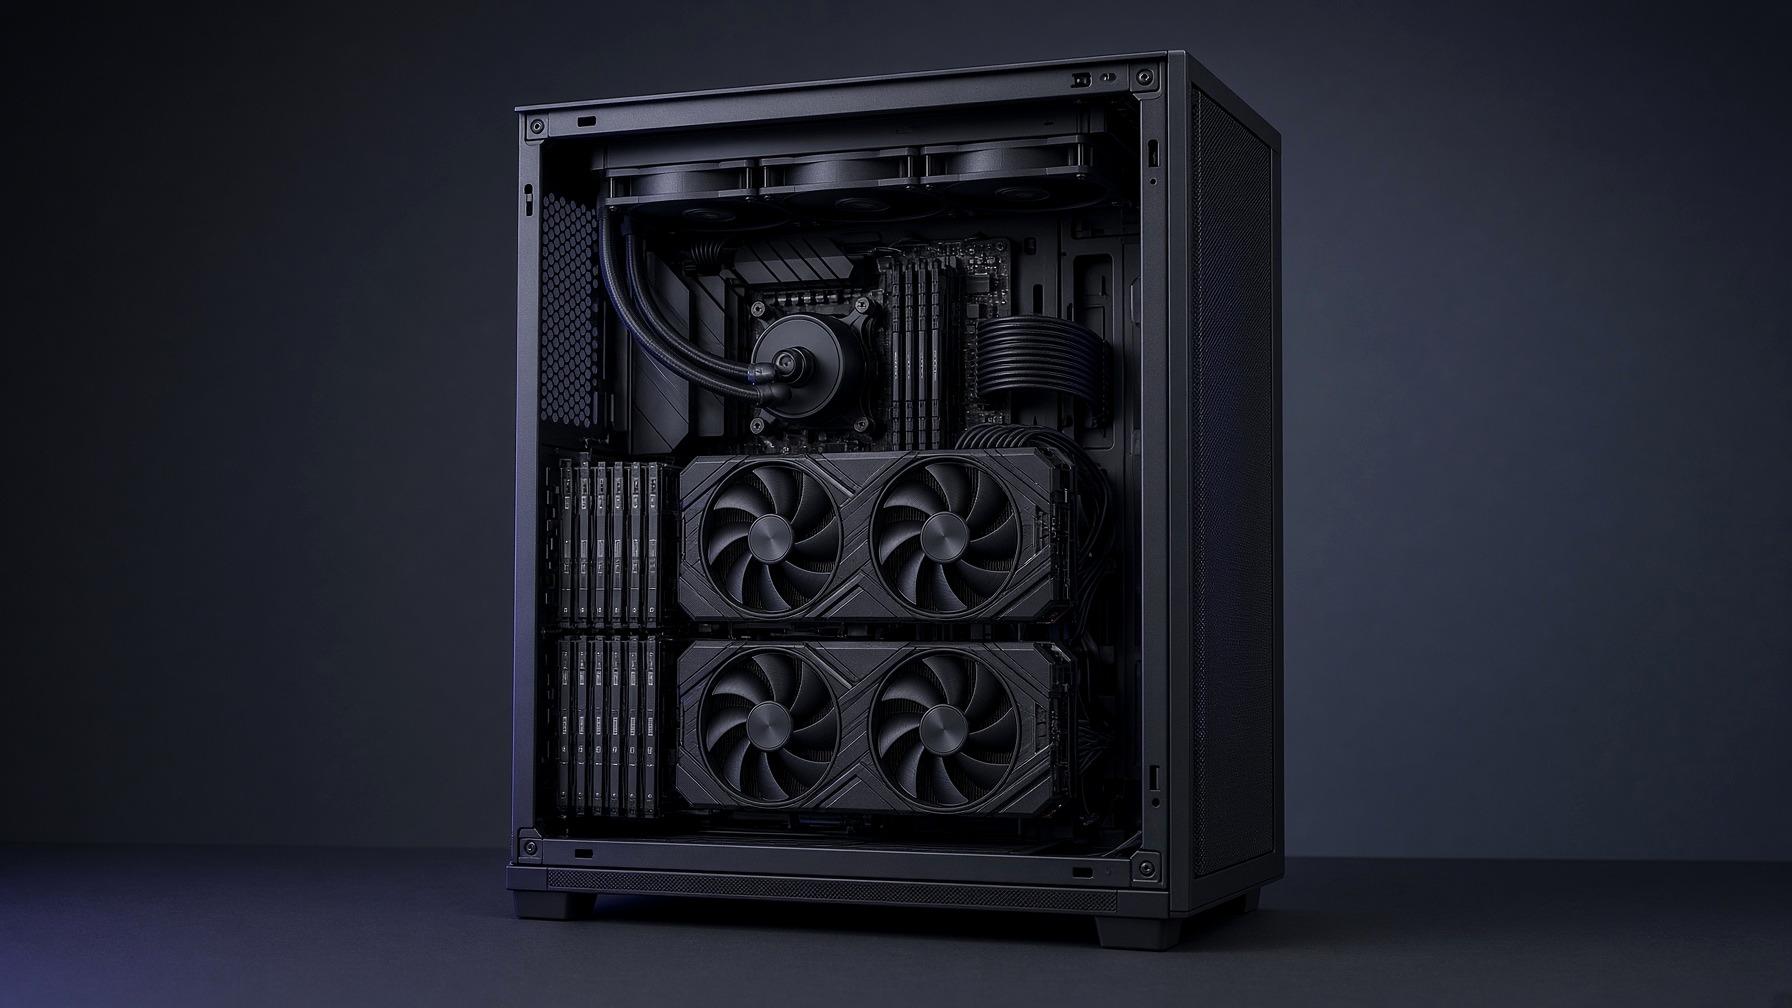
I spec AI-ready PCs for local LLMs: enough VRAM for the quant you want, enough system RAM for context, and cooling that holds sustained token generation without thermal collapse. Gaming leftover parts are usually the wrong shape for this job.
Tell me the models, context length and whether you also game or create on the same box. I’ll tell you whether a tune of what you already have is enough, or whether the spend belongs in a different GPU.